September. Another month, another model menu.
Astra is here, and naturally the first temptation is to select it for everything. The hardest architecture problem. The awkward migration. The tiny job that changes three words in a document. All of it.
But hang on. What are we actually paying for?
This is the third AI Model Pricing Watch: a UK view of direct API token prices. It follows July and August. This month I have expanded the shortlist to 26 model entries across eight providers, including Astra and newer alternatives. The categories are shopping baskets, not intelligence scores.
Checked on 8 September 2026. The tables show US-dollar rates as the providers publish them, alongside fixed workload costs in pounds. These are API prices, not the number of tokens included in a ChatGPT, Codex, Claude or Cursor subscription.
September in a minute
- Astra enters at $10 input and $50 output per million tokens. Sol remains available at a lower promotional rate.
- Sol's standard uncached reference basket is 25% cheaper in dollars than August. That is a genuine same-model price change.
- Sonnet 5 stays at $2 input and $10 output. Its previously announced September increase has been cancelled.
- Fable 5.1, Gemini 3.8 Flash, Grok 4.6, Kimi K2.7 Code and Qwen3.8 are on the menu. New models get new entries, not invented August prices.
- DeepSeek now needs a time-of-day label. Peak and off-peak prices are different.
The supporting provider pages are linked in the tables and the notes below. My practical conclusion has not changed: buy the least expensive route to a result you can actually use. Sometimes that is the more capable model. Sometimes it absolutely is not.
Astra arrives. Sol gets cheaper.
OpenAI's 3 September API changelog records GPT-6 Astra's release. Its model page lists standard prices of $10 for input, $1 for cache hits and $50 for output per million tokens. Cache writes are separate, at $12.50 per million.
On our large basket of 250,000 uncached input tokens and 25,000 output tokens, that is $3.75, or about £2.77. Sol costs $1.50, or about £1.11, for the same token counts. That makes Astra 2.5 times the token bill in this particular uncached example. It does not mean it costs 2.5 times as much to finish the same real job.
The 21 August announcement reduced Sol to $4 input and $20 output. Its current model page says the promotional price is available at least through 21 November 2026. That is not a promise it ends the next day.
For our basket, Sol falls from $2 to $1.50 before currency conversion. I would test Astra on the jobs where wrong turns are expensive, then measure the whole run against Sol. I would not promote every background task just because the dropdown has a new name.
The September price tables
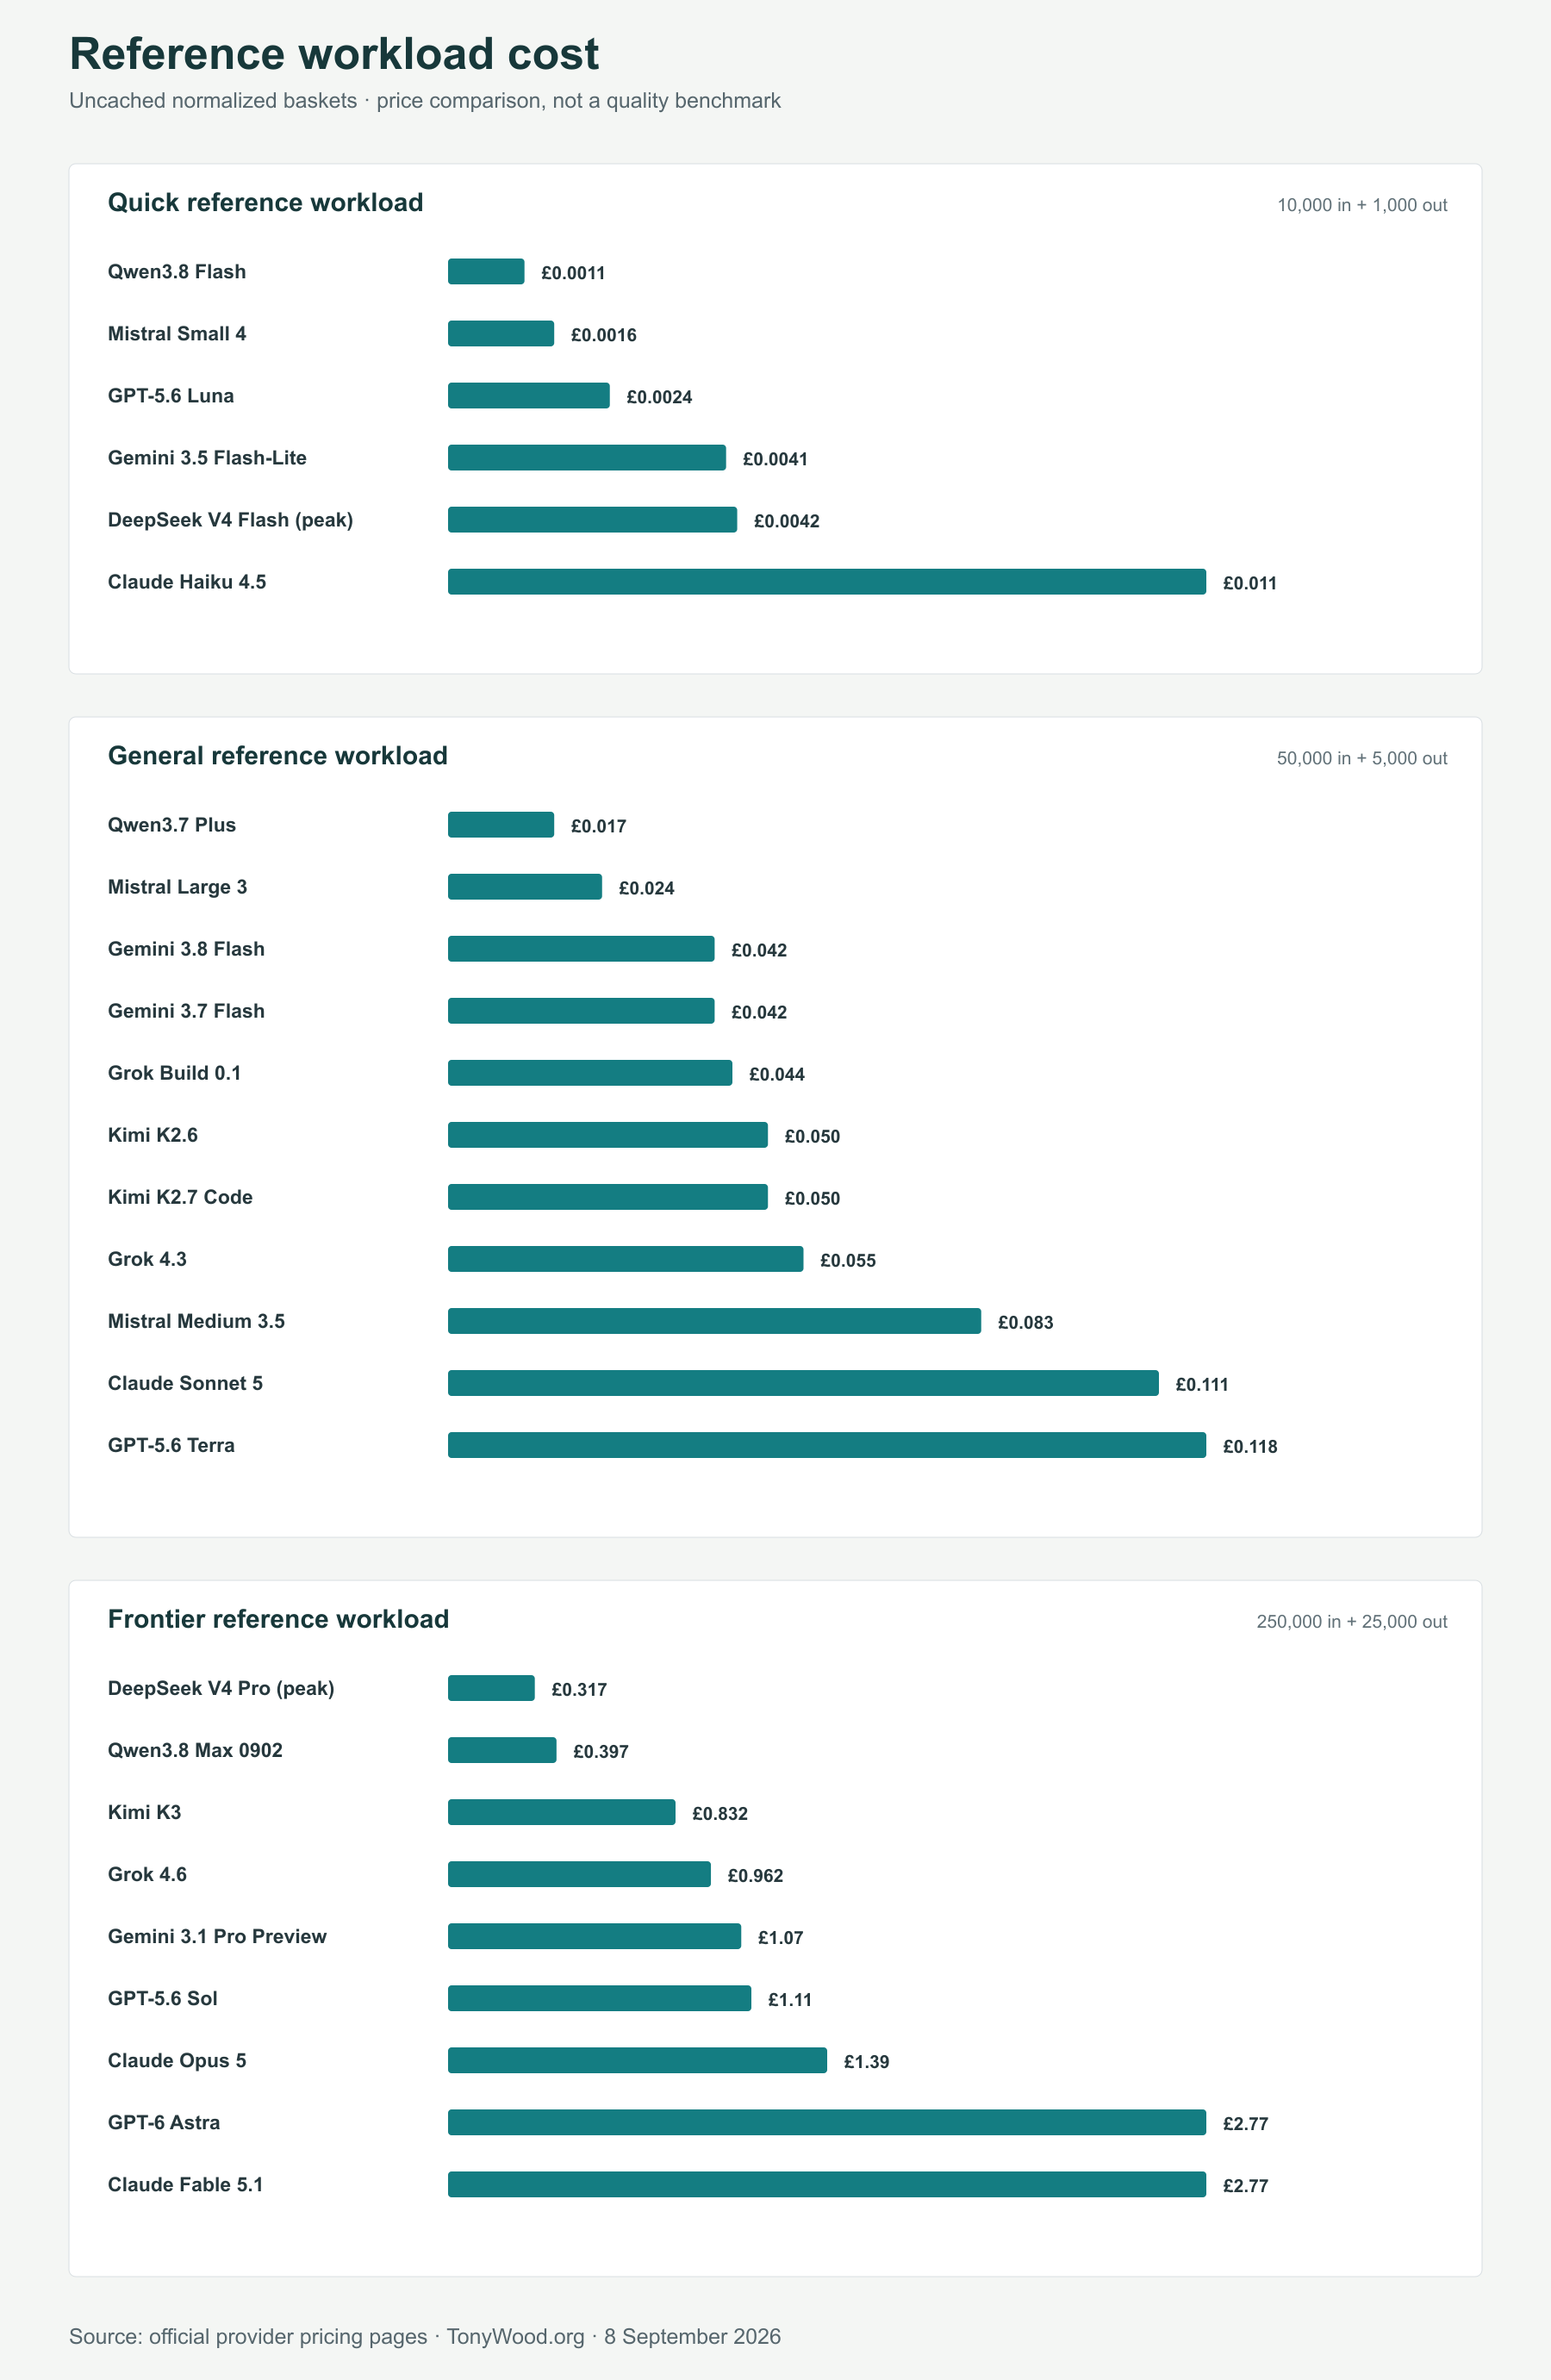
All input prices below are uncached standard text-input rates. Cache-hit prices are for eligible repeated input, not every prompt. Output includes billable reasoning where the provider charges for it. A token is a billing unit, not a universal quantity of useful work: different models can tokenise the same text differently.
Every basket uses the same token counts as previous editions. For the large basket, Gemini 3.1 Pro and Grok 4.6 cross their 200K input threshold, so the basket uses their more expensive long-context rates even though the table's rate columns show the starting tariff. Astra and Sol do not cross OpenAI's 272K input threshold: 250K input plus 25K output is not 275K input.
Quick: 10,000 input + 1,000 output tokens
| Model / source | Input $/1M | Cache hit $/1M | Output $/1M | Basket £ |
|---|---|---|---|---|
| GPT-5.6 Luna | 0.20 | 0.02 | 1.20 | 0.00237 |
| Claude Haiku 4.5 | 1 | 0.10 | 5 | 0.01110 |
| Gemini 3.5 Flash-Lite | 0.30 | 0.03 | 2.50 | 0.00407 |
| Mistral Small 4 | 0.15 | Not tabulated | 0.60 | 0.00155 |
| DeepSeek V4 Flash (peak) | 0.44 | 0.014 | 1.32 | 0.00423 |
| Qwen3.8 Flash | 0.113 | Not tabulated | 0.382 | 0.00112 |
General: 50,000 input + 5,000 output tokens
| Model / source | Input $/1M | Cache hit $/1M | Output $/1M | Basket £ |
|---|---|---|---|---|
| GPT-5.6 Terra | 2 | 0.20 | 12 | 0.11838 |
| Claude Sonnet 5 | 2 | 0.20 | 10 | 0.11099 |
| Gemini 3.8 Flash | 0.75 | 0.075 | 3.75 | 0.04162 |
| Gemini 3.7 Flash | 0.75 | 0.075 | 3.75 | 0.04162 |
| Grok 4.3 | 1.25 | 0.20 | 2.50 | 0.05549 |
| Grok Build 0.1 | 1 | 0.20 | 2 | 0.04439 |
| Mistral Large 3 | 0.50 | Not tabulated | 1.50 | 0.02405 |
| Mistral Medium 3.5 | 1.50 | Not tabulated | 7.50 | 0.08324 |
| Kimi K2.6 | 0.95 | 0.16 | 4 | 0.04994 |
| Kimi K2.7 Code | 0.95 | 0.19 | 4 | 0.04994 |
| Qwen3.7 Plus | 0.32 | Not tabulated | 1.28 | 0.01657 |
Frontier: 250,000 input + 25,000 output tokens
| Model / source | Input $/1M | Cache hit $/1M | Output $/1M | Basket £ |
|---|---|---|---|---|
| GPT-6 Astra | 10 | 1 | 50 | 2.77462 |
| GPT-5.6 Sol | 4 | 0.40 | 20 | 1.10985 |
| Claude Fable 5.1 | 10 | 0.25 | 50 | 2.77462 |
| Claude Opus 5 | 5 | 0.50 | 25 | 1.38731 |
| Gemini 3.1 Pro Preview | 2 | 0.20 | 12 | 1.07285 |
| Grok 4.6 | 2 | 0.50 | 6 | 0.96187 |
| DeepSeek V4 Pro (peak) | 1.32 | 0.044 | 3.96 | 0.31742 |
| Kimi K3 | 3 | 0.30 | 15 | 0.83239 |
| Qwen3.8 Max 0902 | 1.65 | Not tabulated | 4.951 | 0.39679 |
Currency: £0.7399 per US dollar, from the Bank of England table dated 4 September 2026 returned during this check. It is an indicative spot rate, not a card-payment quote or a claim about today's executable exchange rate. Multiply any dollar rate by 0.7399 for the corresponding GBP rate. VAT, currency conversion fees, subscriptions, tools, cache storage, cache writes, hosting and retries are outside these uncached baskets.
“Not tabulated” does not mean free or unavailable. I have not assigned a model-specific cache-hit price where the checked card did not supply one clearly enough for this comparison. This is especially relevant to Mistral and Qwen, whose caching arrangements need their own check.
The small print that changes the bill
Anthropic: a cancelled increase and cheaper cache reads
Anthropic's current pricing page says Sonnet 5's $2/$10 introductory input/output price is now standard. The planned increase to $3/$15 on 1 September will not happen. Fable 5.1 costs $10/$50, with cache reads at $0.25; five-minute cache writes cost $12.50 and one-hour writes $20. Those are different operations.
Fable 5.1 is a new version, not evidence that Fable 5's entire tariff fell. Mythos 5.1 has limited availability, so it is noted here rather than presented as an ordinary self-service choice. Opus 5 remains in the tables as a useful lower-priced comparator.
Google: put the promotion in your diary
Gemini 3.7 Flash arrived on 13 August and 3.8 Flash on 2 September. Their standard introductory tariff is $0.75 input, $0.075 cache hit and $3.75 output through 31 December 2026. Google lists $1.50/$0.15/$7.50 from 1 January 2027. Do not build a permanent budget around the temporary figure. Gemini 3.5 Flash-Lite is also newly included in this watch; that does not make it a September release.
Grok, Kimi and Mistral: more useful choices
Grok 4.6 was released on 12 August. At 200K input and above, its tariff rises to $4 input, $1 cached and $12 output. Grok Build 0.1 is included as a coding option. Its smaller context capacity is why it sits in the general basket.
Kimi's cards list K2.7 Code at the same $0.95/$4 input/output rate as K2.6, but with a different cache-hit rate. The coding model requires thinking mode; its high-speed variant is not the price shown here. K3 remains the larger comparator.
Mistral Medium 3.5 is added alongside Small 4 and Large 3. It is an existing model, not a new September launch. The API page also offers third-party GLM 5.2 at $1.40 input, $0.14 cache hit and $4.40 output. That is a Mistral-hosted Z.ai model, so I have kept it outside the direct model-maker comparison rather than quietly call it a Mistral model.
DeepSeek: what time are you running it?
DeepSeek's current card resolves Flash to version 0731 and Pro to 0813. The main tables use peak rates. Off-peak input/cache-hit/output prices are $0.22/$0.007/$0.66 for Flash and $0.66/$0.022/$1.98 for Pro, half the peak rates. Peak hours are Monday to Friday, 01:00–04:00 and 06:00–10:00 UTC; all other hours are off-peak.
That can matter for work which can wait. It does not mean every job is available at the off-peak headline price. The old snapshot did not establish the same version-and-time basis, so these are not plotted as simple like-for-like price increases.
Qwen: the endpoint is part of the price
Qwen's release list includes 3.8 Flash and 3.8 Max 0902. The rates here use Global deployment in Frankfurt for those two. Qwen3.7 Plus retains the Singapore International alias used in August: $0.40/$1.60 list less its published 20% promotion gives $0.32/$1.28. No expiry is specified there. Do not substitute a different region, dated endpoint or nightly discount and call it the same price.
August to September: the lines we can defend
Among the 11 matched entries, one uncached reference basket changed; ten were unchanged between the recorded snapshots. Sol's basket is down 25% in dollars. An unchanged dollar basket is about 0.36% cheaper in pounds using these two FX observations. That small movement is not a provider price cut.
A correction to the previous watch: August treated Haiku 4.5's $0.50/$2.50 input/output figures as standard. They match Anthropic's batch tariff, while its launch announcement and current standard card show $1/$5. I cannot substantiate the earlier standard-price reduction claim. September uses $1/$5 and excludes Haiku from the historical lines; it would be wrong to manufacture a doubling from that baseline.
The original snapshots remain frozen for traceability. New models and newly covered siblings have no invented past. DeepSeek's two entries are excluded because the previous version/time basis is not sufficiently comparable. That leaves 11 matched entries, three explicit exclusions and 12 entries new to this watch.
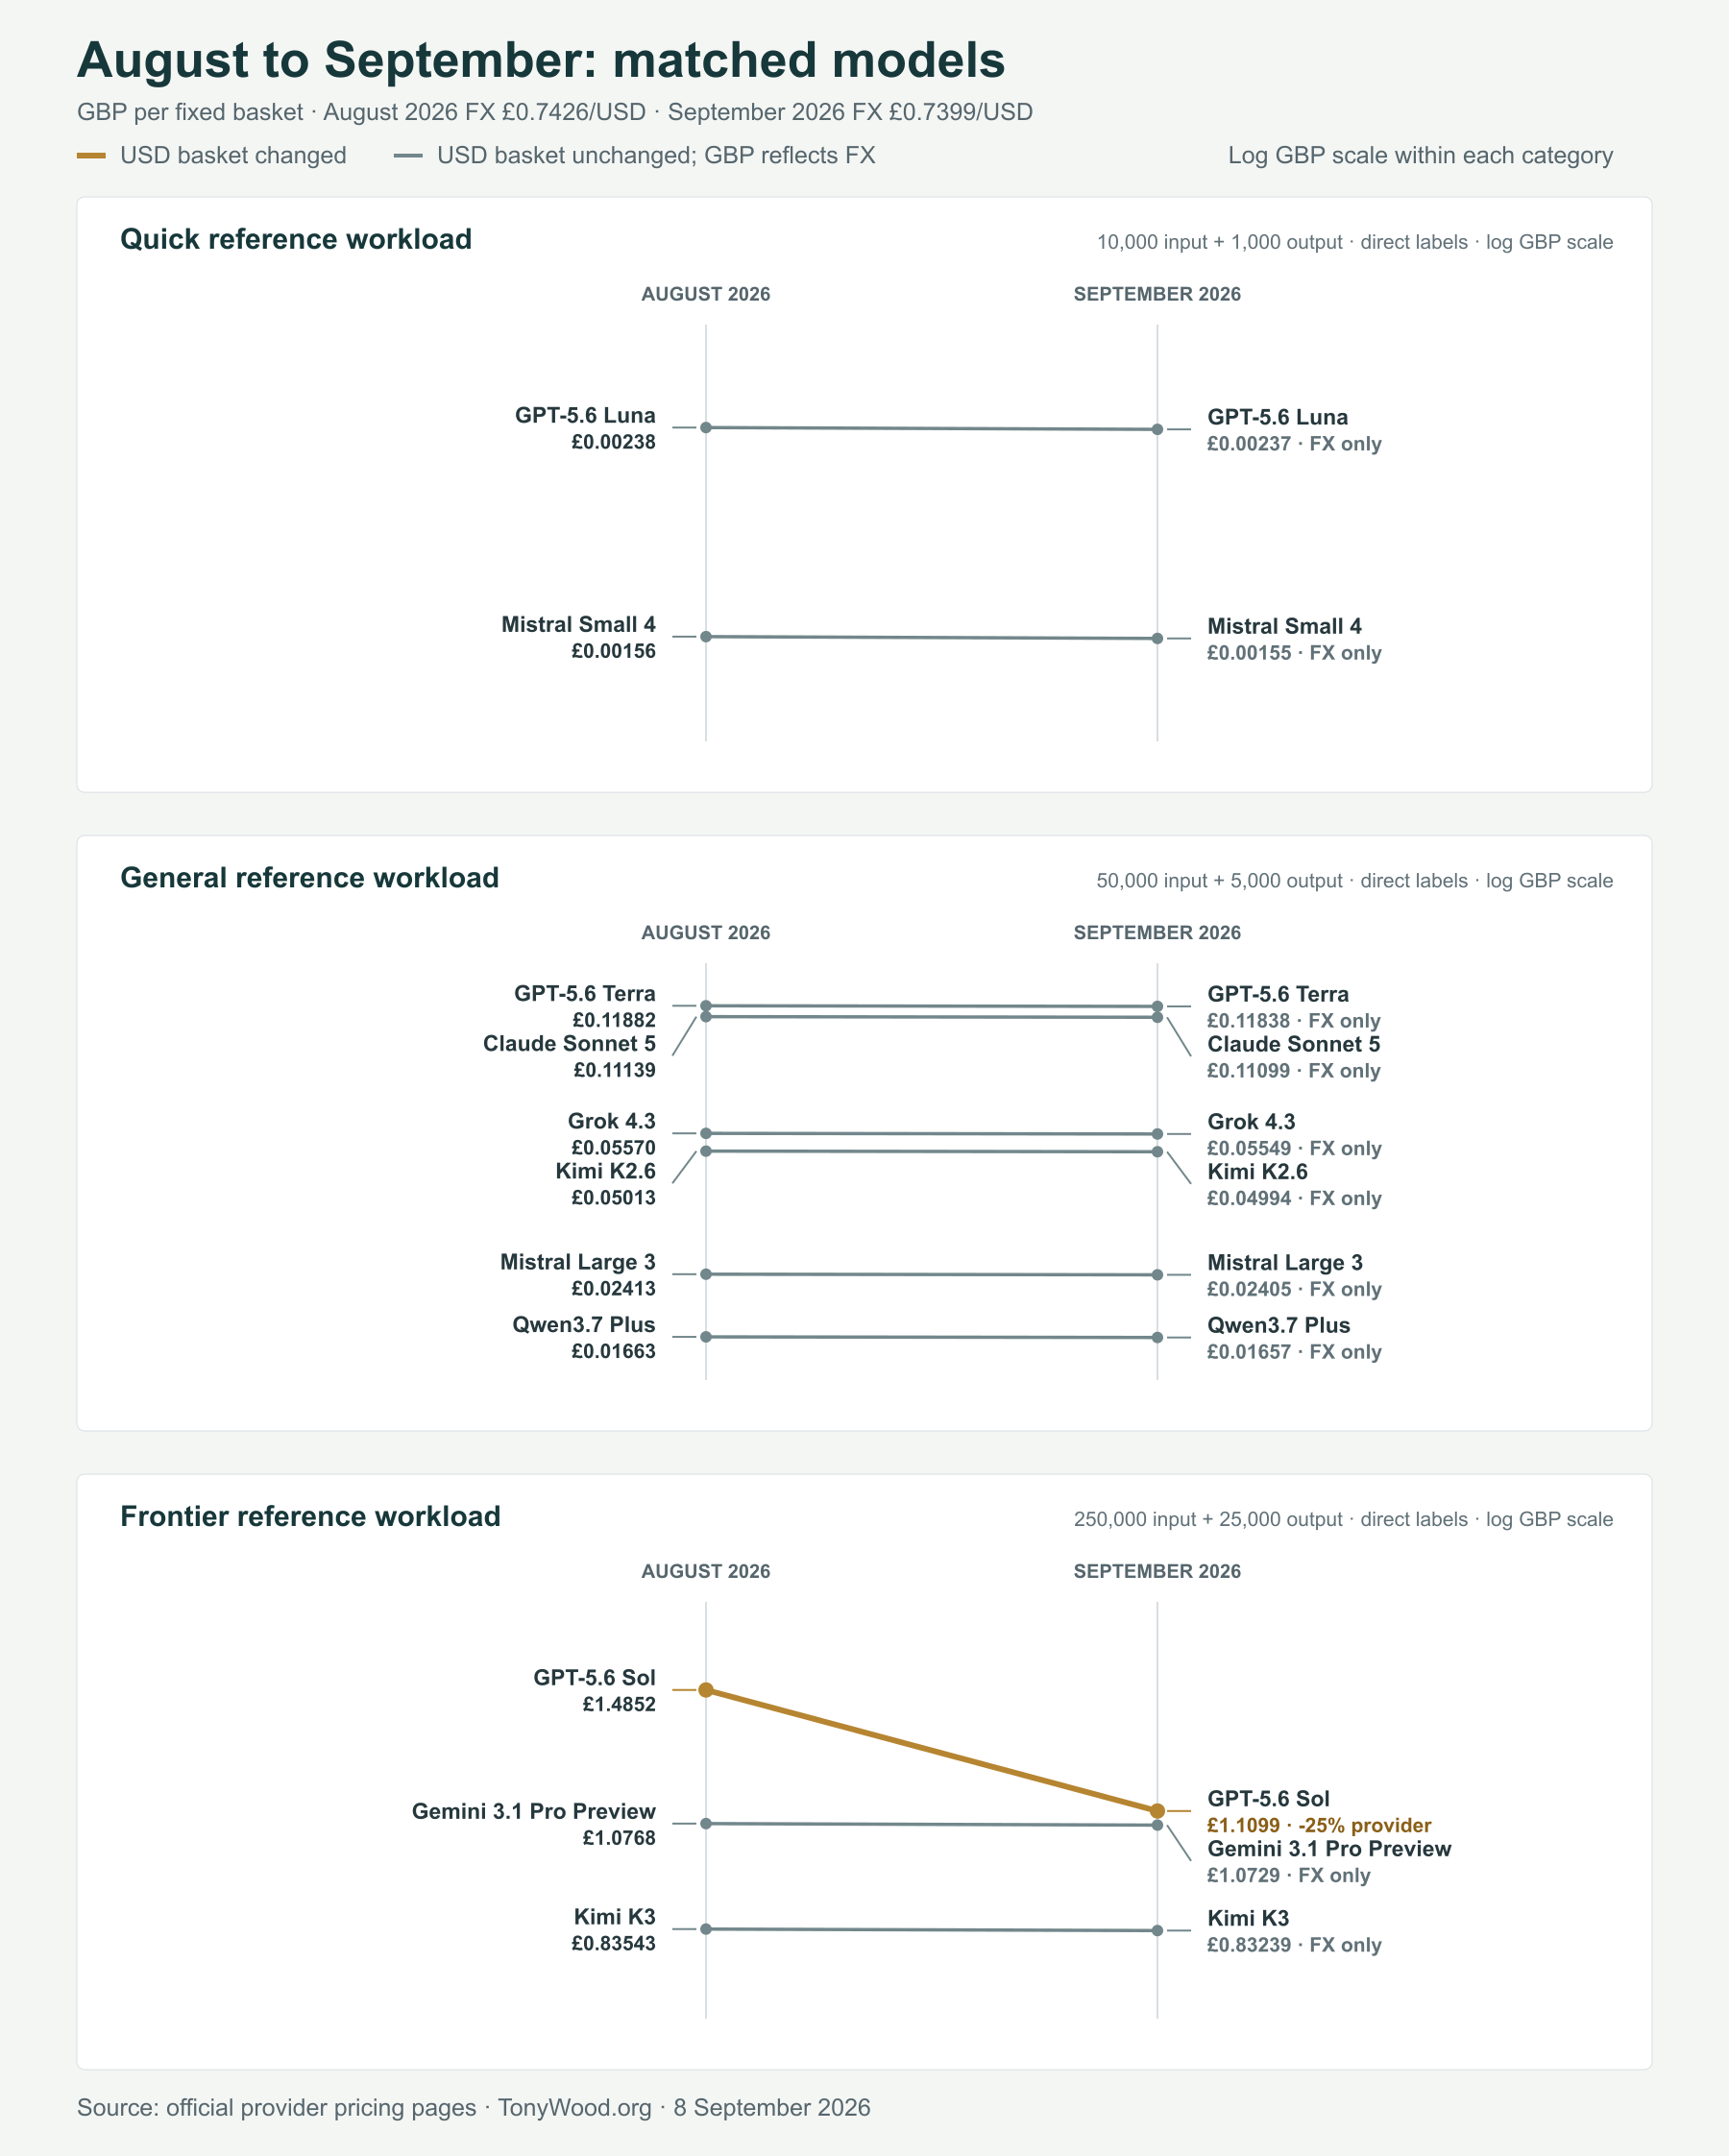
| Category | Provider | Model | August £ | September £ | USD basket change |
|---|---|---|---|---|---|
| Quick | OpenAI | GPT-5.6 Luna | 0.00238 | 0.00237 | Unchanged |
| Quick | Mistral | Mistral Small 4 | 0.00156 | 0.00155 | Unchanged |
| General | OpenAI | GPT-5.6 Terra | 0.11882 | 0.11838 | Unchanged |
| General | Anthropic | Claude Sonnet 5 | 0.11139 | 0.11099 | Unchanged |
| General | xAI | Grok 4.3 | 0.05570 | 0.05549 | Unchanged |
| General | Mistral | Mistral Large 3 | 0.02413 | 0.02405 | Unchanged |
| General | Moonshot AI | Kimi K2.6 | 0.05013 | 0.04994 | Unchanged |
| General | Alibaba Cloud | Qwen3.7 Plus | 0.01663 | 0.01657 | Unchanged |
| Frontier | OpenAI | GPT-5.6 Sol | 1.48520 | 1.10985 | Down 25% |
| Frontier | Gemini 3.1 Pro Preview | 1.07677 | 1.07285 | Unchanged | |
| Frontier | Moonshot AI | Kimi K3 | 0.83542 | 0.83239 | Unchanged |
What I would do with this information
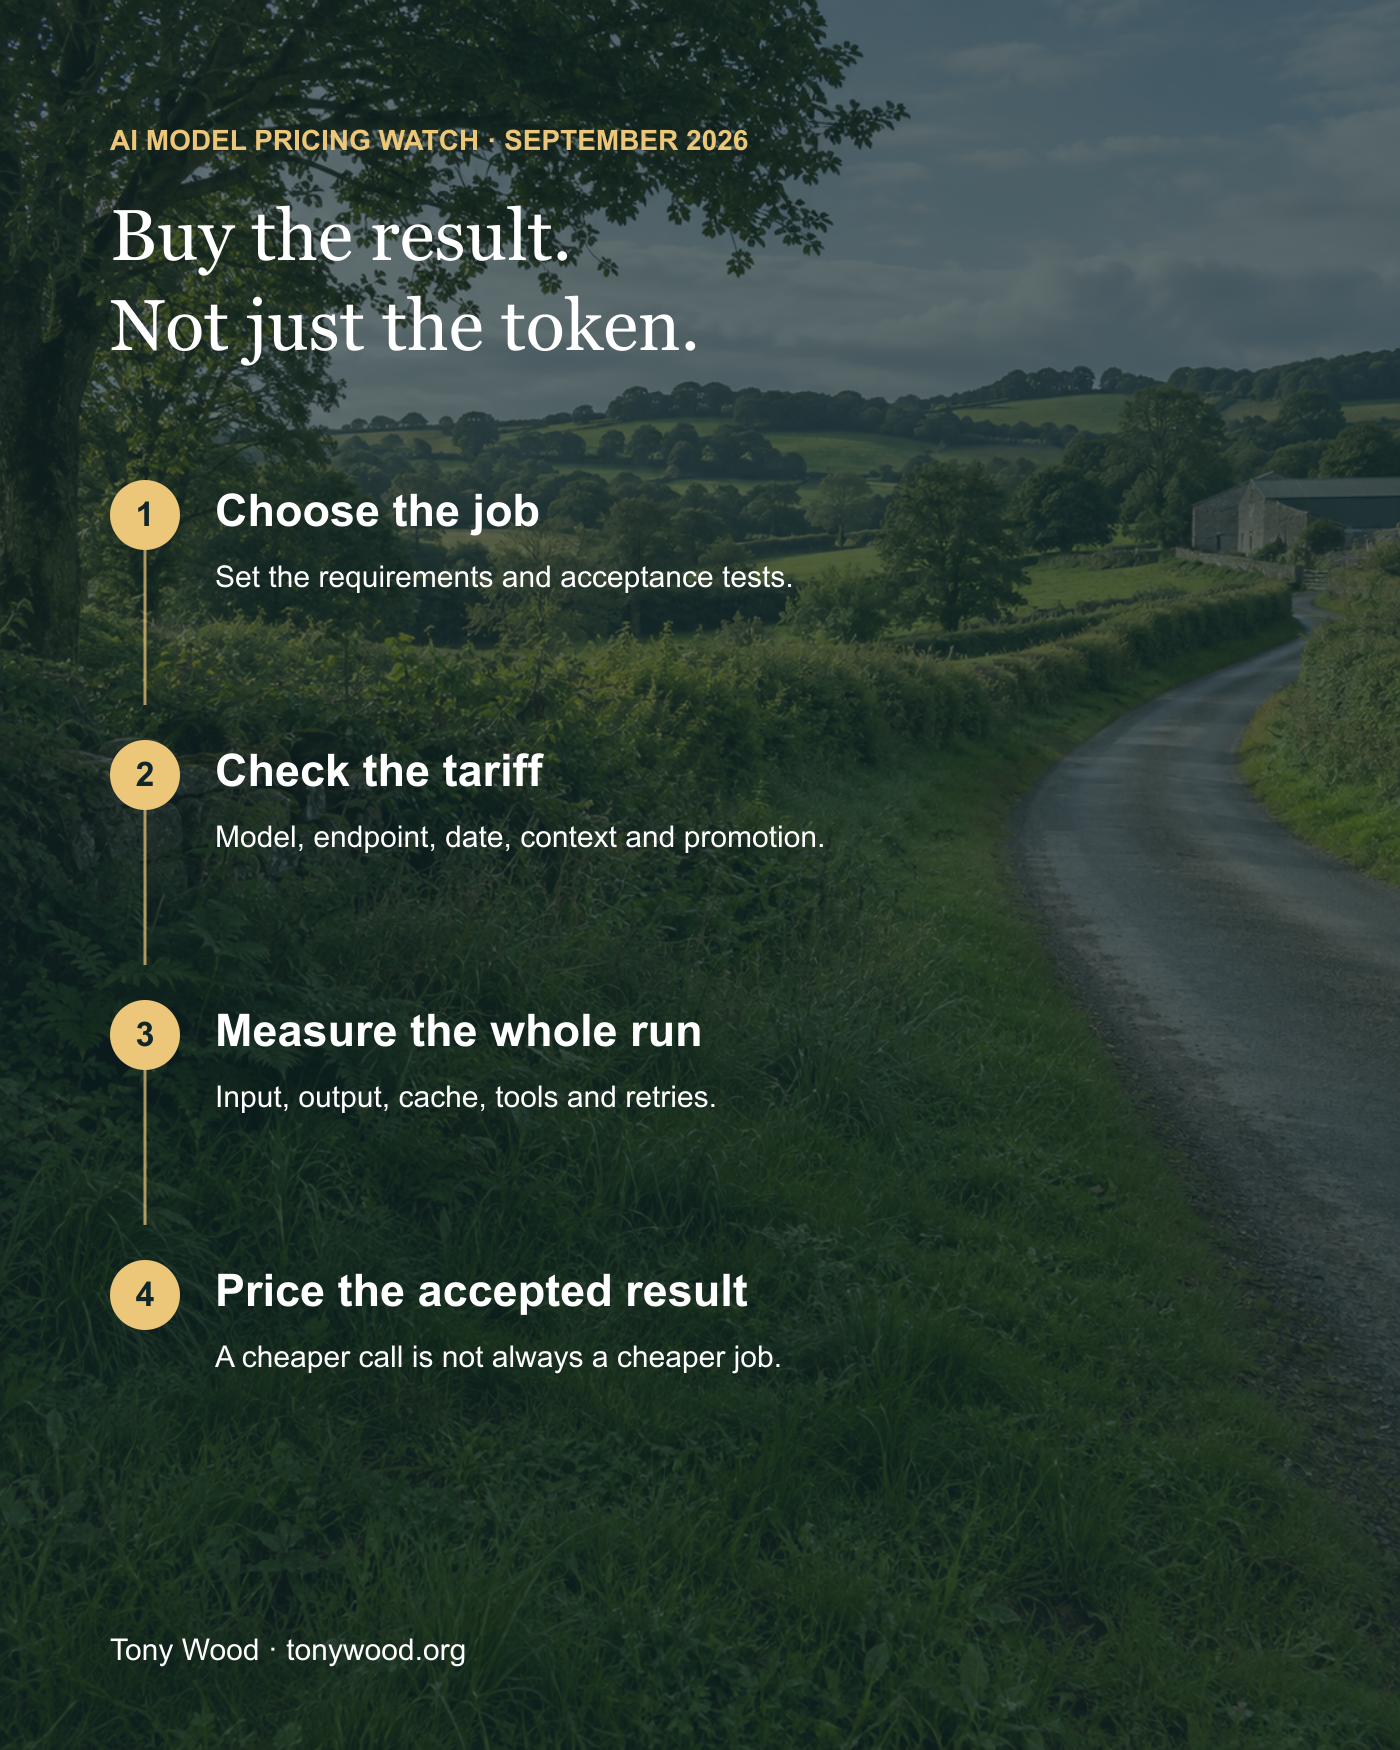
First, look at the actual tasks. Extraction. Classification. Drafting. Coding. Architecture. Checking the work. Those are not all the same job, and they do not all deserve the same model.
I would try the quick group on bounded, repeatable work with clear checks. I would compare the general group on normal delivery tasks. I would test Astra, Fable, Sol and the other larger options when the cost of a bad answer or a failed run justifies it. These are starting points for an evaluation, not promises about which provider wins.
Then measure cost per accepted result. If Astra finishes a task correctly with fewer loops, a higher price per token may still be worth paying. If a smaller model produces the same acceptable result, spending more has not made you cleverer. It has just made the bill bigger.
A useful test prompt for your harness is:
Compare two suitable models on this task. Keep the requirements and acceptance tests the same. Record uncached input, cache hits, cache writes, billable output including reasoning, tool charges, retries, elapsed time and whether the result passed. Recommend the lower-cost reliable route, and explain the uncertainty.
I would also set a spending limit before letting an agent run, and review the model routing monthly. Promotions change. Models change. Yesterday's sensible default can become today's unnecessary expense.
That is the point of this series. Not to crown a winner. To make the choices visible enough that we can spend deliberately.
Astra is welcome. So is a smaller bill.
Related: August's AI Model Pricing Watch, No Astra Yet? Excellent. Another Reset. and The Future Is Either ERP Or AI
Sources and method
This is a dated observation of provider-published prices, not independently audited invoices or a complete catalogue. I checked the previous eight-provider universe and expanded the text/coding shortlist. Image, audio, embedding, specialist cyber, limited-access and high-speed products are not interchangeable with these text-token baskets. Self-hosting costs are also outside this comparison.
Prices were checked against current official rate cards and available release notes. The source links in the tables are the billing authorities for each row; the notes identify promotions, context thresholds and regional exceptions. Calculations use the unrounded stored rates and the stated FX observation. Displayed figures are rounded. The baskets count billable tokens, not equal-length documents, identical quality or guaranteed task completion.
Before committing meaningful spend, check your chosen endpoint, account access, tariff and provider's current terms. This monthly watch is a starting point for that decision, not a substitute for it.