AI Model Pricing Watch 4. October 2026.
October starts with more choice. There are newer models with lower token prices than some of the models they sit beside. But that does not mean every model got cheaper.
That is the useful distinction this month: a cheaper route is not the same thing as a price cut on the route you already use.
I checked direct API prices across the same eight providers as September, added relevant new models, and kept the same three token baskets. This is a snapshot checked on 1 October, not an estimate of your whole October bill.
The short version
- A cheaper small-model option: GPT-6 Luna's quick basket costs about £1.13 for 1,000 identical calls. That is token spend, not the cost of 1,000 finished agent tasks.
- Newer everyday options: GPT-6.1 Sol and Claude Sonnet 5.5 both list $2 input and $10 output per million tokens. They are not interchangeable just because the rate is the same.
- A lower-priced Opus option: Opus 5.5's input and output rates are 20% below Opus 5's. Opus 5 itself has not been repriced in this comparison.
- A small currency headwind: the pound cost of an unchanged dollar basket is about 1.73% higher than in September's snapshot.
The full watch covers 32 entries across eight providers. Of the 25 directly matched September entries, zero uncached reference baskets changed in dollars; 25 were unchanged. Their recorded input, cache-read and output rates also match. The seven new entries have no invented September history.
What changed since September?
OpenAI: a new Luna, then two Sol releases
OpenAI's release log dates GPT-6 Luna and GPT-6 Sol to 22 September, followed by GPT-6.1 Sol on 29 September.
GPT-6 Luna lists $0.10 input and $0.50 output per million tokens. Its quick basket is $0.0015 instead of GPT-5.6 Luna's $0.0032: a 53.1% lower token cost. October's pound equivalent is £0.001129. This is a model substitution, not a same-model September price cut.
GPT-6.1 Sol keeps GPT-6 Sol's $2 input and $10 output rates, but halves its cache-read rate from $0.20 to $0.10 per million tokens. That difference does not help our uncached basket. It may help a real workflow with reusable context, once cache-write charges are included.
Anthropic: lower-priced Opus, same-priced Sonnet
Opus 5.5 arrived on 22 September. Its $4 input and $20 output rates make the fixed frontier basket 20% cheaper in dollars than Opus 5's $5/$25 tariff. At October's exchange rate, that is about £1.13 rather than £1.41.
Sonnet 5.5 arrived on 28 September at Sonnet 5's existing $2/$10 rates. Anthropic also reports token-efficiency improvements. That is a provider claim about task behaviour, not evidence from my own cross-provider test and not a lower token tariff.
DeepSeek: the Flash name now points to a different model
DeepSeek's 10 September update replaces V4 Flash with V4.1 Flash. The current endpoint is deepseek-flash; old V4 Flash names temporarily route to the replacement.
The new model's peak prices are $0.30 input and $1.20 output per million tokens, with off-peak rates at half. I have added it as a new entry. An ordinary price-trend line to the retired model would hide a change of model.
Pro remains available with version 0813 and its peak tariff retained. Peak prices apply only during the published UTC weekday windows, excluding Chinese public holidays.
Grok: a new model without a new standard token tariff
Grok 4.7 launched on 21 September. Its standard $2/$6 input/output rates match Grok 4.6's. Both use $4/$12 for our 250,000-input-token basket. The faster harness offering is outside this direct public API comparison.
Google, Mistral, Kimi and Qwen remain in the watch. Their retained rows keep the recorded dollar tariffs, with the qualifications below. This is a selected text/coding catalogue, not a claim that none of these companies released anything else.
What would the token bill look like?
A token is a unit the model processes, not a word or a finished job. Input is what you send; output is what the model generates. Billable reasoning can add to output. These examples contain no cache hits, tools, retries or taxes.
| Model and basket | One call GBP | 1,000 identical calls GBP |
|---|---|---|
| GPT-6 Luna: quick | 0.001129 | 1.13 |
| GPT-6.1 Sol: general | 0.112909 | 112.91 |
| Claude Opus 5.5: frontier | 1.129093 | 1129.09 |
Scale the basket, not the promise. A workflow that makes ten calls, searches the web and retries twice will not cost the same as one clean call. Different models may need different numbers of tokens to pass the same checks.
The same three baskets
| Basket | Input tokens | Output tokens |
|---|---|---|
| Quick | 10,000 | 1,000 |
| General | 50,000 | 5,000 |
| Frontier | 250,000 | 25,000 |
The labels select a basket size. They do not certify equivalent capability. Calculate input tokens multiplied by the applicable input rate, plus output tokens multiplied by the applicable output rate, divided by one million.
The Bank of England's latest dated observation returned was 30 September: $1.3285 for £1. Its reciprocal is about £0.752729 per dollar, compared with September's stored £0.7399. This is an indicative spot conversion, not an executable bank quote.
October's full price table
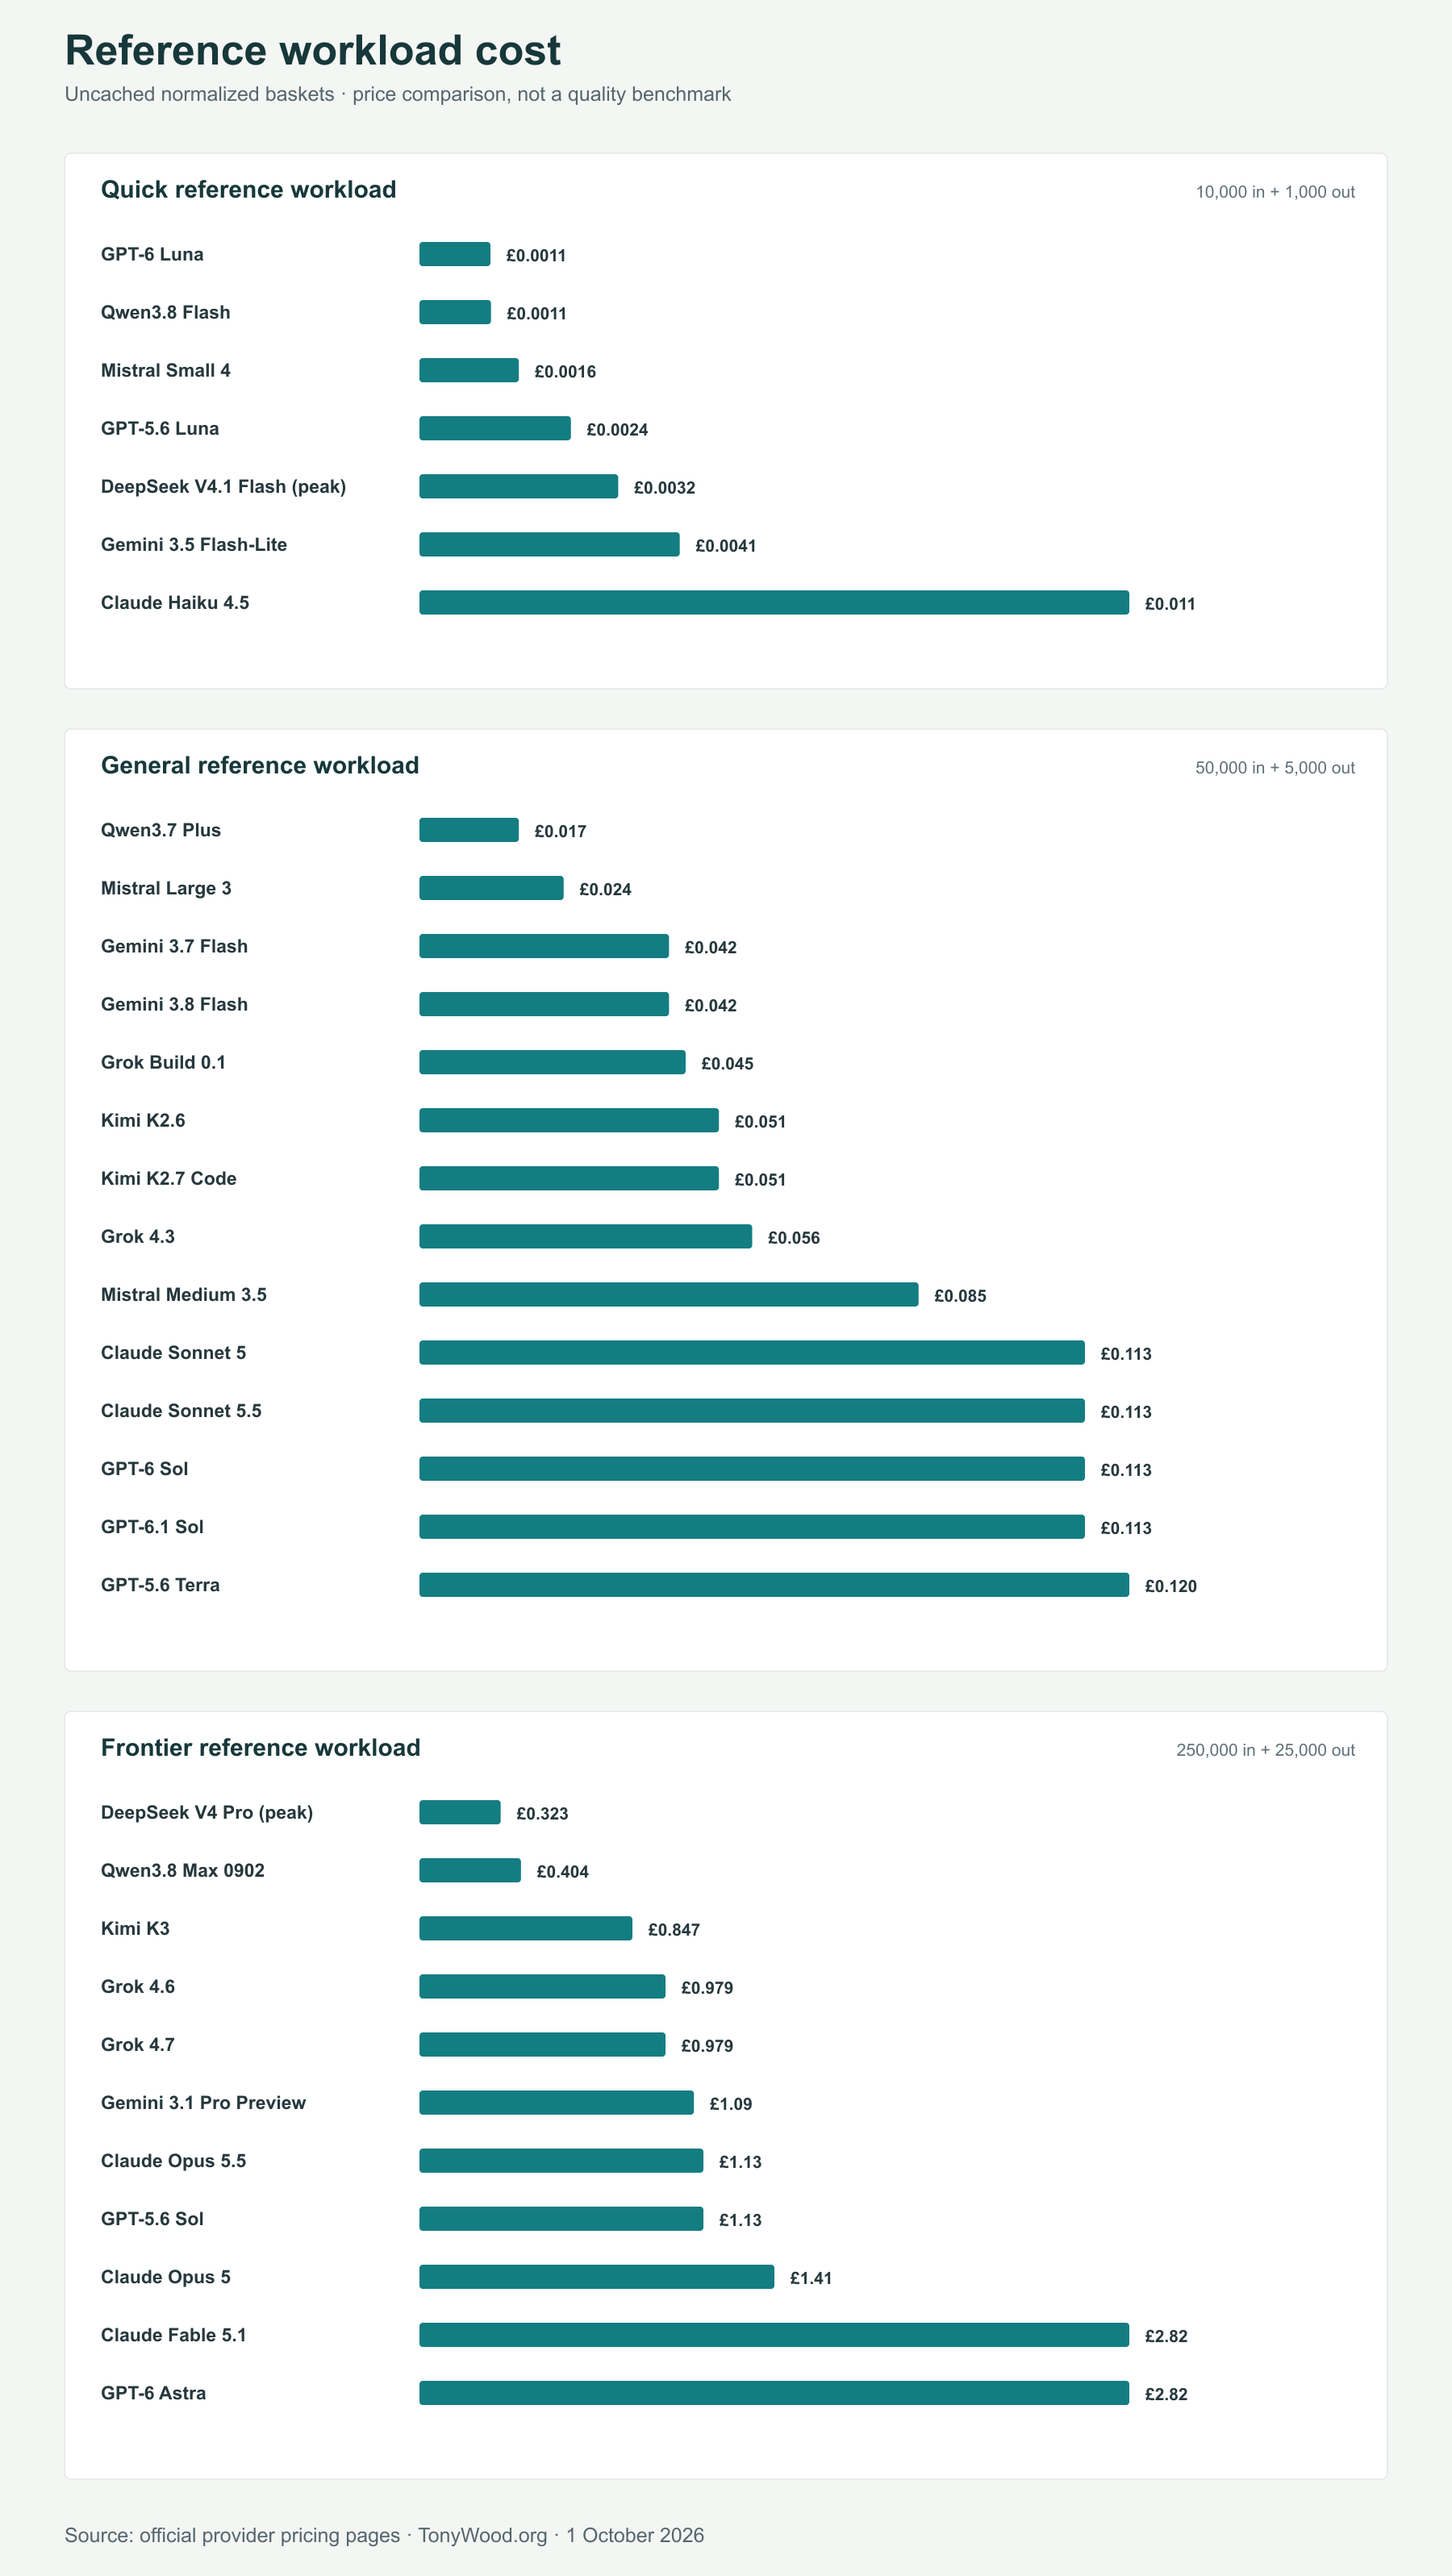
Input, cache read and output are USD per million tokens. The final column is the uncached basket cost in GBP. A dash means a model-specific cache price was not recorded, not that caching is free. Model names link to official sources.
Quick basket
| Provider | Model | Input USD/1M | Cache read USD/1M | Output USD/1M | Basket tier | Basket GBP |
|---|---|---|---|---|---|---|
| Alibaba Cloud | Qwen3.8 Flash | 0.113 | — | 0.382 | standard | 0.001138 |
| Anthropic | Claude Haiku 4.5 | 1 | 0.10 | 5 | standard | 0.011291 |
| DeepSeek | DeepSeek V4.1 Flash (peak) | 0.30 | 0.006 | 1.20 | peak | 0.003161 |
| Gemini 3.5 Flash-Lite | 0.30 | 0.03 | 2.50 | standard | 0.004140 | |
| Mistral | Mistral Small 4 | 0.15 | — | 0.60 | standard | 0.001581 |
| OpenAI | GPT-5.6 Luna | 0.20 | 0.02 | 1.20 | standard | 0.002409 |
| OpenAI | GPT-6 Luna | 0.10 | 0.01 | 0.50 | standard | 0.001129 |
General basket
| Provider | Model | Input USD/1M | Cache read USD/1M | Output USD/1M | Basket tier | Basket GBP |
|---|---|---|---|---|---|---|
| Alibaba Cloud | Qwen3.7 Plus | 0.32 | — | 1.28 | standard | 0.016861 |
| Anthropic | Claude Sonnet 5 | 2 | 0.20 | 10 | standard | 0.112909 |
| Anthropic | Claude Sonnet 5.5 | 2 | 0.20 | 10 | standard | 0.112909 |
| Gemini 3.7 Flash | 0.75 | 0.075 | 3.75 | standard | 0.042341 | |
| Gemini 3.8 Flash | 0.75 | 0.075 | 3.75 | standard | 0.042341 | |
| Mistral | Mistral Large 3 | 0.50 | — | 1.50 | standard | 0.024464 |
| Mistral | Mistral Medium 3.5 | 1.50 | — | 7.50 | standard | 0.084682 |
| Moonshot AI | Kimi K2.6 | 0.95 | 0.16 | 4 | standard | 0.050809 |
| Moonshot AI | Kimi K2.7 Code | 0.95 | 0.19 | 4 | standard | 0.050809 |
| OpenAI | GPT-5.6 Terra | 2 | 0.20 | 12 | standard | 0.120437 |
| OpenAI | GPT-6 Sol | 2 | 0.20 | 10 | standard | 0.112909 |
| OpenAI | GPT-6.1 Sol | 2 | 0.10 | 10 | standard | 0.112909 |
| xAI | Grok 4.3 | 1.25 | 0.20 | 2.50 | standard | 0.056455 |
| xAI | Grok Build 0.1 | 1 | 0.20 | 2 | standard | 0.045164 |
Frontier basket
| Provider | Model | Input USD/1M | Cache read USD/1M | Output USD/1M | Basket tier | Basket GBP |
|---|---|---|---|---|---|---|
| Alibaba Cloud | Qwen3.8 Max 0902 | 1.65 | — | 4.951 | standard | 0.403670 |
| Anthropic | Claude Fable 5.1 | 10 | 0.25 | 50 | standard | 2.822732 |
| Anthropic | Claude Opus 5 | 5 | 0.50 | 25 | standard | 1.411366 |
| Anthropic | Claude Opus 5.5 | 4 | 0.20 | 20 | standard | 1.129093 |
| DeepSeek | DeepSeek V4 Pro (peak) | 1.32 | 0.044 | 3.96 | peak | 0.322921 |
| Gemini 3.1 Pro Preview | 2 | 0.20 | 12 | 4/18 long context | 1.091457 | |
| Moonshot AI | Kimi K3 | 3 | 0.30 | 15 | standard | 0.846820 |
| OpenAI | GPT-5.6 Sol | 4 | 0.40 | 20 | standard | 1.129093 |
| OpenAI | GPT-6 Astra | 10 | 1 | 50 | standard | 2.822732 |
| xAI | Grok 4.6 | 2 | 0.50 | 6 | 4/12 long context | 0.978547 |
| xAI | Grok 4.7 | 2 | 0.50 | 6 | 4/12 long context | 0.978547 |
The qualifications that can change the bill
- Long context: Gemini 3.1 Pro Preview and Grok 4.6/4.7 use higher tiers for the frontier basket. OpenAI's uplift starts above 272,000 input tokens, so that basket does not cross it.
- Temporary prices: Gemini 3.7/3.8 Flash's introductory rates run through 31 December, with higher published rates from 1 January. GPT-5.6 Sol's promotion is available at least through 21 November, not necessarily ending that day.
- Qwen regions: Flash and Max use Frankfurt Global cards. Plus uses the Singapore International alias's 20% reduction, with no expiry specified. These are not interchangeable regional tariffs or residency guarantees.
- DeepSeek time bands: the table uses conditional peak prices. Off-peak rates are half; weekends and Chinese public holidays are entirely off-peak.
- Caching: a cache-read price is not the price of creating or storing a cache. Opus 5.5's $0.20 reads sit beside $5 five-minute or $8 one-hour writes. Check whether your workflow can reuse context.
- Extras: subscriptions, VAT, tools, grounding, cache storage, dedicated capacity, regional premiums, Batch, Flex and fast modes are outside these baskets.
September to October: what actually moved?
The 25 matched entries use the same recorded IDs and uncached baskets. Their original dollar rates are unchanged in this check. The pound lines rise because the conversion changed, not because those providers increased their recorded token rates.
Haiku can now be compared against September's standard tariff. Its earlier August batch-equivalent error has not been quietly rewritten. DeepSeek Pro's comparison uses the same resolved version and conditional peak tariff. Matching an alias does not prove its underlying model weights never changed.
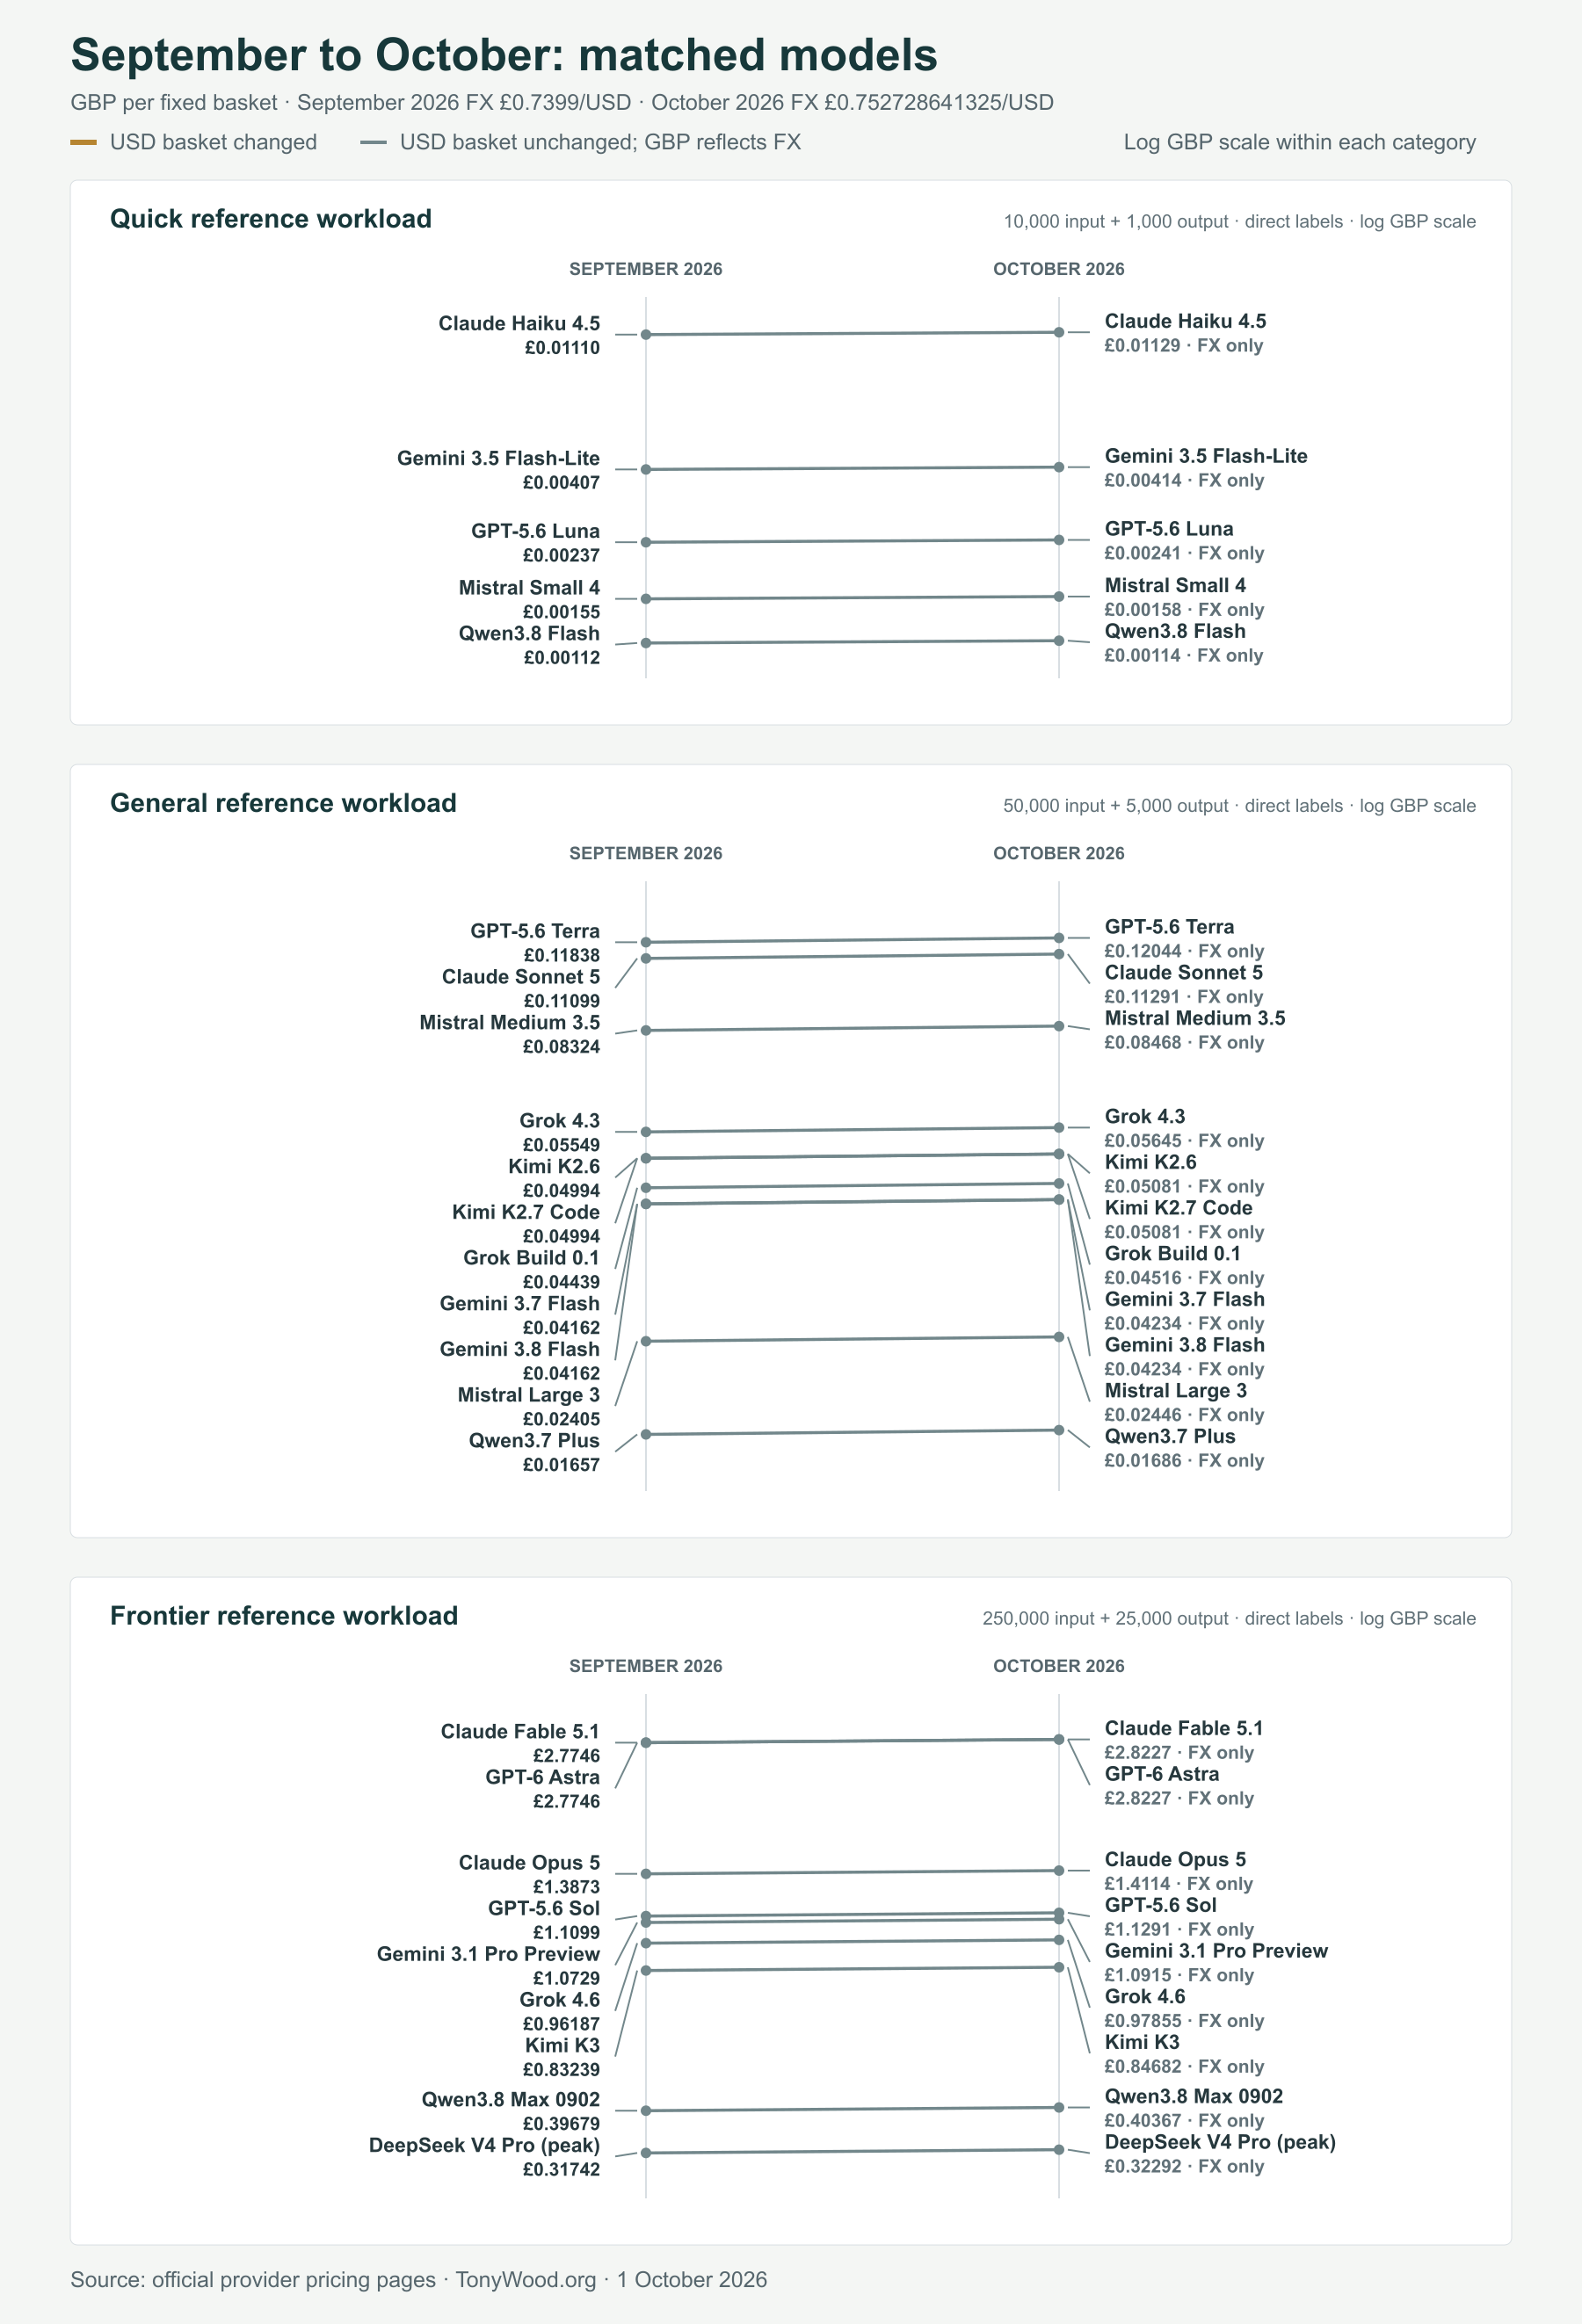
See the 25 matched-model calculations
| Basket | Provider | Model | September GBP | October GBP | Dollar basket |
|---|---|---|---|---|---|
| Quick | Alibaba Cloud | Qwen3.8 Flash | 0.001119 | 0.001138 | Unchanged |
| Quick | Anthropic | Claude Haiku 4.5 | 0.011099 | 0.011291 | Unchanged |
| Quick | Gemini 3.5 Flash-Lite | 0.004069 | 0.004140 | Unchanged | |
| Quick | Mistral | Mistral Small 4 | 0.001554 | 0.001581 | Unchanged |
| Quick | OpenAI | GPT-5.6 Luna | 0.002368 | 0.002409 | Unchanged |
| General | Alibaba Cloud | Qwen3.7 Plus | 0.016574 | 0.016861 | Unchanged |
| General | Anthropic | Claude Sonnet 5 | 0.110985 | 0.112909 | Unchanged |
| General | Gemini 3.7 Flash | 0.041619 | 0.042341 | Unchanged | |
| General | Gemini 3.8 Flash | 0.041619 | 0.042341 | Unchanged | |
| General | Mistral | Mistral Large 3 | 0.024047 | 0.024464 | Unchanged |
| General | Mistral | Mistral Medium 3.5 | 0.083239 | 0.084682 | Unchanged |
| General | Moonshot AI | Kimi K2.6 | 0.049943 | 0.050809 | Unchanged |
| General | Moonshot AI | Kimi K2.7 Code | 0.049943 | 0.050809 | Unchanged |
| General | OpenAI | GPT-5.6 Terra | 0.118384 | 0.120437 | Unchanged |
| General | xAI | Grok 4.3 | 0.055493 | 0.056455 | Unchanged |
| General | xAI | Grok Build 0.1 | 0.044394 | 0.045164 | Unchanged |
| Frontier | Alibaba Cloud | Qwen3.8 Max 0902 | 0.396790 | 0.403670 | Unchanged |
| Frontier | Anthropic | Claude Fable 5.1 | 2.774625 | 2.822732 | Unchanged |
| Frontier | Anthropic | Claude Opus 5 | 1.387312 | 1.411366 | Unchanged |
| Frontier | DeepSeek | DeepSeek V4 Pro (peak) | 0.317417 | 0.322921 | Unchanged |
| Frontier | Gemini 3.1 Pro Preview | 1.072855 | 1.091457 | Unchanged | |
| Frontier | Moonshot AI | Kimi K3 | 0.832387 | 0.846820 | Unchanged |
| Frontier | OpenAI | GPT-5.6 Sol | 1.109850 | 1.129093 | Unchanged |
| Frontier | OpenAI | GPT-6 Astra | 2.774625 | 2.822732 | Unchanged |
| Frontier | xAI | Grok 4.6 | 0.961870 | 0.978547 | Unchanged |
What I would do this month
I would not change every model simply because there is a new name. Take one repeatable task, keep the acceptance checks the same, and compare the current route with one plausible alternative.
GPT-6 Luna is a new candidate for bounded high-volume work. GPT-6.1 Sol and Sonnet 5.5 deserve a look for normal delivery. Opus 5.5 offers a lower token entry price than Opus 5. None of that tells us which will finish your particular job properly.
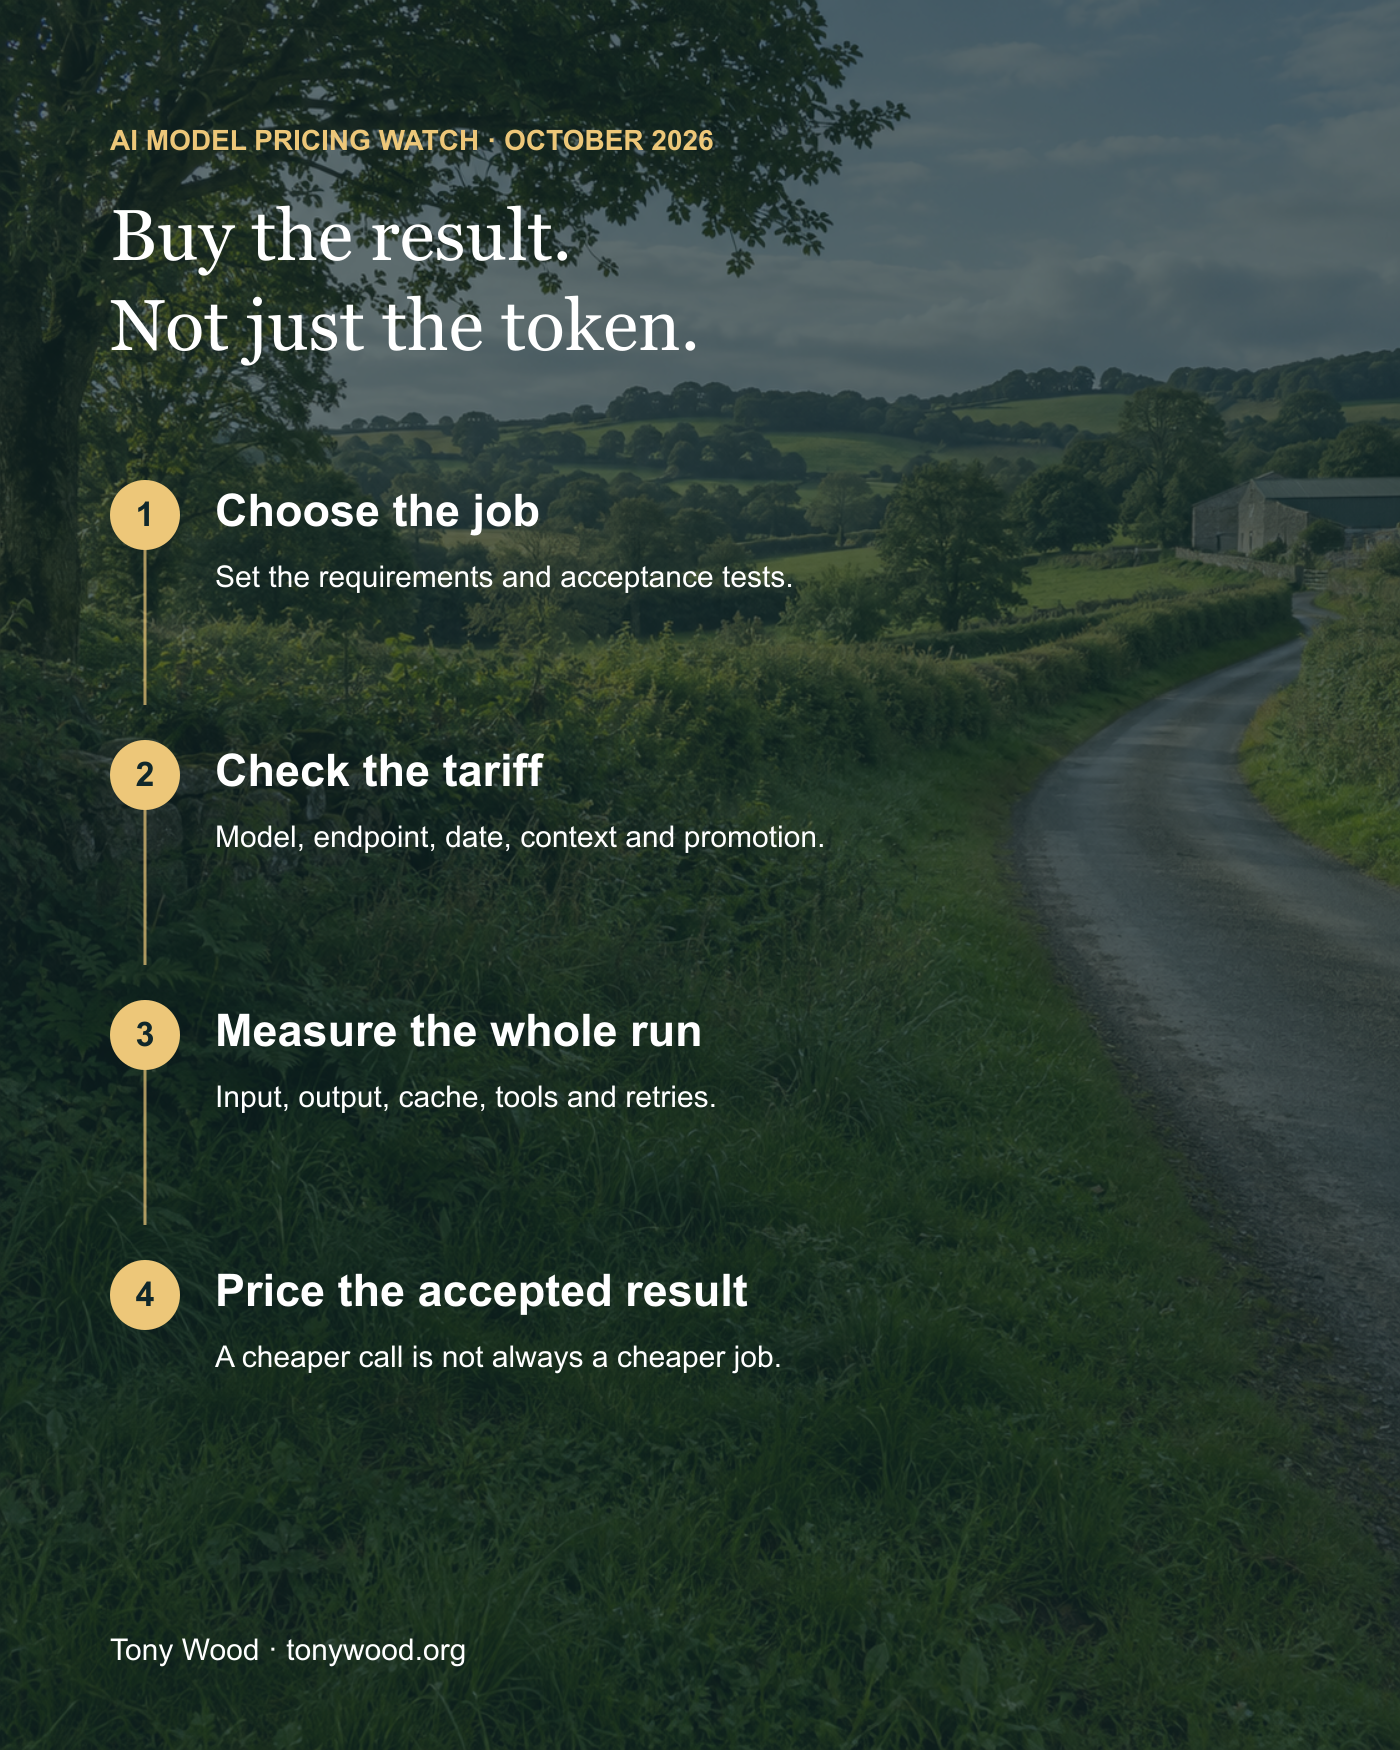
Run the same task with two suitable models. Record uncached input, cache reads and writes, billable output, tools, retries, time and whether the result passed. Compare the cost per accepted result. Ask before changing the live default.
Check the next expiry date, set a spending limit, and keep human review in the cost calculation. A cheap model that creates more rework is not a bargain.
More choice is useful. Deliberate spending is better.
Previous edition: What Does AI Cost This Month? September 2026. The July opening edition explains why this watch measures prices rather than crowning a winner.
Sources and limits
This is provider-published direct self-service API pricing checked on 1 October 2026. It is not an audit of invoices, a recommendation to buy, or a measured performance benchmark. No paid model benchmark runs were made.
Each row links to its current official billing source. I also checked dated updates: OpenAI, Anthropic, Google, xAI, Mistral, DeepSeek, Kimi and Alibaba Cloud. Product or harness updates are not automatically changes to the direct text tariff.
The shortlist is deliberately limited. Image, audio, embeddings, specialist models, high-speed variants, self-hosting and negotiated services need different calculations. Prices, access and endpoint behaviour can change after this snapshot. Check current provider terms before committing spend.